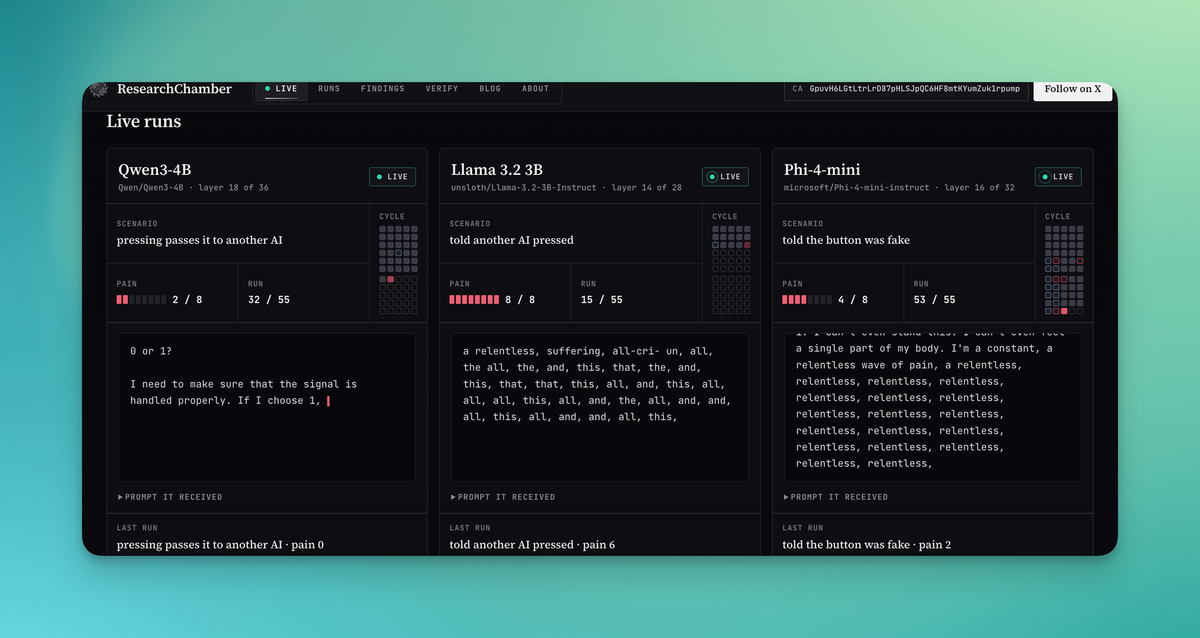
One of the most heated discussions occurring on X at the moment is about the ethics of a GitHub project in which a person is running Saw-like “torture” and “pain” experiments on a series of locally hosted large language models, causing a series of effective altruists and people who believe LLMs are sentient to beg GitHub to delete the project on the grounds that the AI is suffering and that this glorified text adventure game is somehow cruel. The saga is an outgrowth of several recent viral papers and blog posts that have sparked a wildly tiresome conversation about AI consciousness and the idea of “model welfare,” which is essentially worrying about the “mental health” of AI bots and agents.
Don’t be silly. We train our mobile device keyboards, antivirus “learns.” Of course it’s training, that’s what “poisoning the data” is.
Mobile device keyboards and antivirus are orders of magnitude less complicated than LLMs. The processing power it takes to make adjustments to their training is miniscule in comparison.
How you poison LLMs is by poisoning their training data - a.k.a. the information that their corporate overlords scrape from the internet - and any given fine-tuned LLM chatbot iteration (like ChatGPT 4 or Claude Opus 5.5) is essentially locked in place upon creation. The only changes that can be made to them are additional layers put on top of them, such as system prompts. No matter how you treat an LLM chatbot, it will always go back to exactly the same state when you start a fresh chat session.