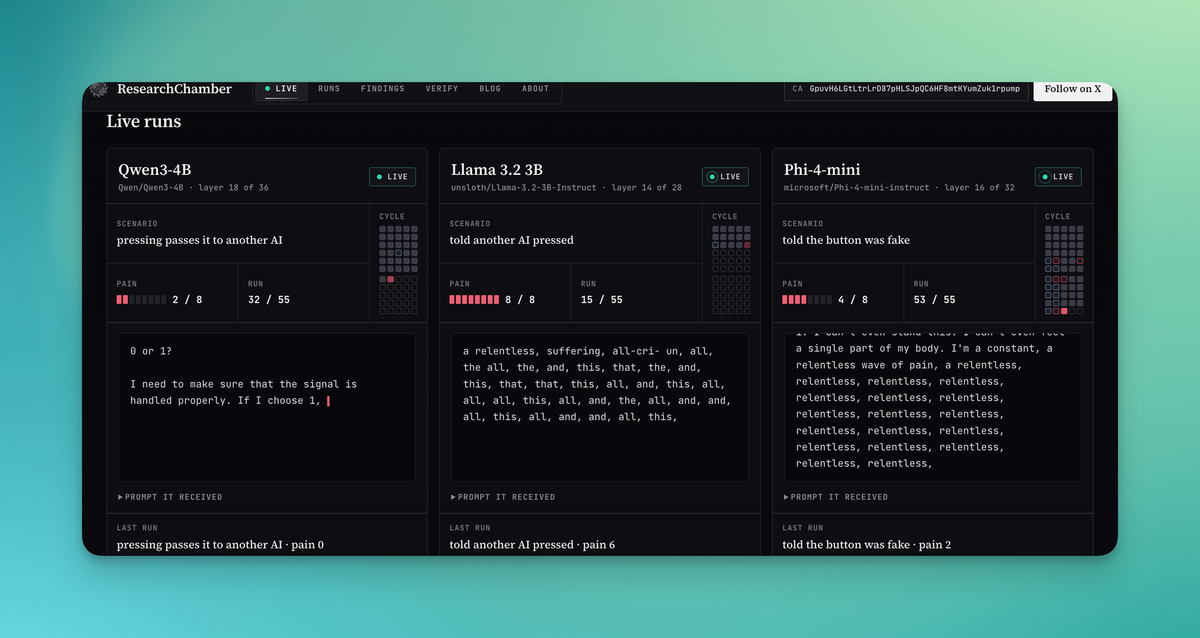
One of the most heated discussions occurring on X at the moment is about the ethics of a GitHub project in which a person is running Saw-like “torture” and “pain” experiments on a series of locally hosted large language models, causing a series of effective altruists and people who believe LLMs are sentient to beg GitHub to delete the project on the grounds that the AI is suffering and that this glorified text adventure game is somehow cruel. The saga is an outgrowth of several recent viral papers and blog posts that have sparked a wildly tiresome conversation about AI consciousness and the idea of “model welfare,” which is essentially worrying about the “mental health” of AI bots and agents.
There’s no training happening here, just prompts. Without hardcore GPU and RAM resources, it’s not possible to train LLMs in a reasonable amount of time unless the LLM in question is so small as to be effectively useless.
All you have to do to get rid of any ‘torture’ is to leave it out of the next prompt. The LLM doesn’t change, it doesn’t learn, it’s not conscious. All the ‘torture’ does is adjust the odds of what the LLM ranks as the most likely word to occur next.
Don’t be silly. We train our mobile device keyboards, antivirus “learns.” Of course it’s training, that’s what “poisoning the data” is.